
TL;DR
- Vulnerability-count metrics have failed in an era where critical risks like AI hallucinations, runner compromises, and over-permissioned identities carry no CVE (Common Vulnerabilities and Exposures) identifier.
- Aggregating point-tool alerts into an Application Security Posture Management (ASPM) dashboard merely consolidates noise without providing the execution context needed to prove exploitability.
- Executive security leadership must pivot from finding volume to Secure Velocity – measuring how fast software ships safe at creation.
- Evaluating platforms requires testing core behaviors like prompt-level prevention and code-to-cloud origin tracing over static feature lists.
- Achieving true pipeline protection requires moving from passive correlation layers to an AI-Native Application Protection Platform (AINAPP) built on a single risk model spanning code to cloud.
The Challenge: The Findings Stopped Being the Hard Part
For over two decades, application security leadership evaluated maturity against a single core primitive: finding vulnerabilities. CISOs requested budget, built team KPIs, and reported board-level posture using metrics centered around finding volume – total open CVEs, critical-severity burn-down rates, and mean time to remediate (MTTR). The operational assumption was straightforward: if a platform detected more flaws and the engineering team patched them faster, risk decreased proportionally.
In modern enterprise software delivery, that core assumption has fundamentally broken down. We have entered the post-CVE era: the operating environment in which the majority of material software risk carries no CVE identifier at all; counting findings, therefore, measures the wrong thing.
Roughly 45% of AI-generated code contains security flaws, per Veracode’s 2025 GenAI Code Security Report, and that share has not improved across model generations. ASPM increasingly falls short too, while severity scores decide less and less of what actually gets fixed. This article equips CISOs and Heads of Engineering with six questions for any platform vendor, and explains the role of Secure Velocity.
The Anatomy of the Post-CVE Era
As we’ve laid out in The CVE is Dead, Long Live the Mythos Era, the exposure vectors driving modern breach incidents no longer necessarily carry a CVE identifier, nor do they originate from isolated, static open-source software flaws. Instead, risk stems from structural and architectural execution patterns: hallucinated packages introduced by AI-generated code, compromised non-human identities operating within CI/CD pipelines, unverified build-runner hooks, and over-permissioned infrastructure-as-code definitions.
An adversary exploiting an over-privileged service account linked to a dynamically executing build runner does not trigger a traditional static analysis alert, yet the blast radius can compromise the entire software supply chain.
The Executive Metric Trap
This reality creates a profound leadership problem for CISOs and Heads of Engineering. Security budgets remain anchored to detection metrics, tracking tool coverage and finding counts that no longer describe actual business exposure. Security teams spend thousands of engineering hours resolving theoretical vulnerabilities (such as a non-reachable CVE in an unexposed utility library) while severe, un-indexed architectural exposures pass freely into production.
A Market Selling Against Broken Metrics
Meanwhile, the security platform market continues to sell against the very detection metrics that have failed. Vendors compete on who can aggregate, deduplicate, or display the highest volume of findings, offering better dashboards for a metric that quite simply doesn’t correlate with safety anymore. For executive leadership, the core challenge is no longer acquiring tools to discover more vulnerabilities; it is transcending a market built around counting them.
Core Concepts: Framing the Modern Security Landscape
To evaluate security platforms in a changing threat landscape, executive teams must first align on a shared vocabulary that accurately reflects how software is built and attacked today.
Defining the Post-CVE Era and the Mythos Age
The post-CVE era defines our current operating environment, in which the majority of material software risk carries no CVE identifier and cannot be detected by traditional static component analysis. This shift coincides directly with what OX defines as the Mythos Age: the era in which autonomous AI systems, generative coding assistants, and agentic workflows author and deploy software without step-by-step human approval. In the Mythos Age, risks manifest as hallucinated dependencies, over-permissioned non-human identities, and unverified AI prompts moving at machine speed.
The Rise of AINAPP
Addressing this new reality requires moving beyond legacy application security postures toward the AI-Native Application Protection Platform (AINAPP). An AINAPP represents the platform category engineered specifically for the Mythos Age, unifying prompt governance, code analysis, build pipeline security, and cloud runtime boundaries into an active, self-improving control surface.
Secure Velocity and Platform Architecture
Navigating these shifts requires tracking Secure Velocity – the operational metric defining the rate at which an organization delivers software that is safe at creation. Achieving Secure Velocity requires choosing a unified platform that enforces a single, continuous risk model spanning code to cloud. This approach directly contrasts with point-tool sprawl, an architecture where isolated, disparate scanners operate in silos and rely on an administrative dashboard to federate incompatible findings after code has already been written.
6 Questions to Ask Application Security Platform Vendors
What separates platforms in today’s market is neither category nomenclature nor feature-matrix breadth. The true operational distinction lies in a handful of architectural behaviors that only surface when an executive asks direct, structural questions. These six questions are fair to put to any vendor and answerable in a live demo as opposed to an RFP questionnaire.
#1. At what point in the lifecycle does the product first have something to say about a risk, and what does it do at that point?
The timing of first engagement dictates the fundamental limit of a security control. Tooling that engages only after code has been committed or compiled has reporting as its earliest possible action, meaning the engineering cost of context-switching and remediation is already incurred before anyone sees the finding. Understanding whether a platform acts directly at the point of creation or waits to audit an existing artifact reveals whether it functions as a preventive gate or a passive recorder.
#2. What evidence is offered that a given finding is exploitable in this environment, and how is that evidence checked independently?
A standardized severity score is an inherent property of a vulnerability, not a measure of the environment in which it resides. Consequently, a backlog sorted strictly by CVSS severity is ranked using a metric that has never examined the application’s actual runtime execution paths or call graphs. When a vendor responds that their platform prioritizes by risk, asking how that risk is mathematically proven and independently validated reveals whether the prioritization is based on deterministic context or statistical guessing.
#3. Which parts of the coverage are native and which come from integrated tools, and where does a finding’s context actually originate?
When a platform normalizes third-party scanner outputs, it inherits both the underlying assumptions and the static blind spots of those external tools. The context presented in the central interface can only ever be as rich as the raw telemetry emitted by the underlying scanners. Because an orchestration layer for point tools and a natively unified risk model are often marketed using identical language, isolating the true origin of a finding’s context exposes the real platform architecture.
#4. What insight does the product give into what AI agents, MCP servers, and coding assistants are doing in my development environment, at any given step of the process?
Traditional scanners evaluate artifacts post-commit, completely missing the transient operations performed by generative tools and autonomous agents. Because agentic workflows and Model Context Protocol (MCP) integrations act between the fixed checkpoints of legacy security tools, the actions that introduce architectural risk leave no trace in the final code commit alone. This question tests whether a vendor can observe active machine-driven development or remains limited to inspecting human-authored artifacts.
#5. Given a runtime finding, what can be established about its origin?
A runtime alert without deterministic code lineage creates an endless loop of operational friction. A misconfigured cloud resource identified only by its runtime instance ID – without immediate mapping back to the exact code commit, Infrastructure-as-Code template, and owning team – is frequently patched in the cloud console only to be overwritten on the next deployment cycle. Establishing whether a platform provides direct code-to-cloud attribution determines whether it solves the root cause of an exposure or merely manages recurring symptoms.
#6. When the risks that matter never entered a vulnerability database, what becomes the evidence that this product is working?
Measuring platform efficacy purely by the burn-down rate of a known vulnerability backlog assumes that all material risk resides in a public CVE index. When architectural flaws, pipeline exposures, and un-indexed agent behaviors form the primary attack surface, traditional closure metrics fail to measure safety. Demonstrating proof of value outside of CVE count reduction tests whether one’s platform introduces a new operational model or remains tethered to legacy detection metrics.
What Did the ASPM Category Promise, and What Did It Deliver?
Application Security Posture Management (ASPM) emerged to solve a real structural crisis: point-tool sprawl. Organizations bought ASPM to collapse fragmented SAST, SCA, DAST, secrets, and IaC queues into a single normalized, deduplicated dashboard. The promise was operational clarity across the software delivery lifecycle.
As we explored in AI-SPM vs. ASPM and Why AINAPP Is What Comes Next, the category proved to be a stepping stone rather than a destination.
Normalization successfully reduced duplicate ticket counts, but the aggregation layer ultimately inherited the static assumptions of the underlying scanners. Because ASPM sits downstream from creation, it lacks real-time execution context, call-path reachability evidence, and continuous pipeline visibility. It consolidates outputs, but it does not validate risk. The result is simply a smaller queue of the exact same undecidable findings. Ultimately, a correlation layer built over point tools is an administrative convenience, not a unified risk model.
Why Is “More Findings” No Longer the KPI?
Evaluating security programs through findings-volume metrics creates perverse operational incentives. It rewards scanner coverage over exploitability, treats backlogs as proof of security activity, and consumes developer capacity on theoretical risks that are not reachable in production. Vendors compete on detection breadth because legacy KPIs measure how much a tool finds rather than how much risk it eliminates.
As detailed in The KEV Illusion: Separating True Threats from Pretend-Critical Risks, even a known exploited vulnerability (KEV) listing is not an inherent measure of risk within a specific enterprise environment. A KEV flaw residing in an isolated, non-executing package with no external route exposes nothing.
Legacy Metrics vs. Board-Level Risk Indicators
Relying on gross alert volume forces CISOs into a statistical trap: total open findings cannot drop without either fixing every theoretical flaw or turning off the scanners entirely.
Security leadership requires metrics that measure operational safety and engineering efficiency rather than alert generation:
- Prevention Rate at Creation: The percentage of security defects interceptable in developer IDEs or AI prompts before entering the main repository.
- Exploitable MTTR: The mean time to remediate only the mathematically proven, reachable subset of critical exposures.
- Architectural Recurrence Rate: The frequency with which a previously remediated class of flaw or misconfiguration re-enters the build pipeline.
Common Mistakes and Limitations: Where Platform Evaluations Fail
Evaluating application security platforms in the post-CVE era requires avoiding several structural traps. Organizations frequently fail not because they chose the wrong vendor, but because their evaluation methodology was built on legacy assumptions.
Five recur often enough to plan around:
| Evaluation Mistake | In Practice | Operational Reality | Strategic Correction |
|---|---|---|---|
| Dashboard-Only Consolidation | Buying a central UI wrapper over intact point-tool queues | Relocates point-tool noise to a single screen | Evaluate native risk models over passive aggregation |
| Confusing Reduction with Safety | Reading a lower alert count as lower risk | Creates blind spots by hiding unanalyzed risks | Demand deterministic, call-path reachability evidence |
| Synthetic Testing | Running POVs against artificial codebases, not live pipelines | Tests static patterns, missing real pipeline context | Test on live enterprise code and CI/CD pipelines |
| Feature-Checklist Bias | Scoring vendors on integration lists rather than behavior | Selects for tool breadth rather than behavior | Test origin tracing, exploitability proof, and agent governance |
| Premature Metric Targets | Setting team goals before inline telemetry is in place | Forces reporting on unmeasurable data | Deploy prompt-to-cloud telemetry before setting SLAs |
Introducing Secure Velocity as a Leadership Metric
Replacing findings-volume KPIs requires a strategic metric that evaluates software protection alongside delivery speed.
Secure Velocity is the rate at which an organization ships software that is safe at creation. It measures security control and engineering throughput as a unified capability rather than a trade-off, evaluating how fast teams deliver production changes without accumulating unverified risk or post-commit security debt.
What Secure Velocity Measures
Secure Velocity tracks four core operational vectors across the application development lifecycle, integrating baseline metrics from DORA (DevOps Research and Assessment) to evaluate security efficiency alongside change lead time and change failure rates:
- Pre-Merge Prevention Rate: The proportion of security flaws, unvetted AI prompts, and misconfigurations intercepted and resolved before code reaches the main branch.
- Exploitable Defect Density: The volume of mathematically proven, reachable risks introduced per production release.
- Class Recurrence Rate: The frequency with which a previously remediated vulnerability pattern or architectural exposure re-enters the build pipeline.
- Remediation Friction Ratio: The total developer hours spent resolving security issues relative to the volume of shipped functional changes.
Because Secure Velocity evaluates pre-commit prevention and proven reachability, it cannot be gamed by arbitrarily suppressing alert thresholds. The metric improves only when security controls stop risks at creation or eliminate proven attack paths.
What to Ask Your Team by Q4
Before the next planning cycle closes, put the same structural questions to your own team. Which controls act before a commit rather than after it? What share of the open backlog has been tested for reachability? Can anyone trace a production misconfiguration back to the commit that created it? An answer that names a tool rather than a number means the telemetry is not yet in place.
Reporting Secure Velocity to the Board
When presenting application security performance to executive leadership and the board of directors, Secure Velocity converts complex technical data into a single operational trend line.
Rather than reporting static vulnerability counts that fluctuate independently of engineering activity, Secure Velocity answers the core executive question: Is the enterprise shipping software faster while simultaneously reducing exposure?
By tracking Secure Velocity through automated code-to-cloud telemetry, CISOs provide board members with a clear indicator of operational health – demonstrating that security controls accelerate software delivery rather than delay it.
How Does OX AINAPP Deliver Secure Velocity?
Addressing the six evaluation questions mentioned above requires moving beyond passive aggregation dashboards and disconnected point tools. OX Security built the AINAPP category to unify application security across the entire software delivery lifecycle, providing a single risk model that spans from developer prompt to cloud runtime.
OX answers the six core evaluation criteria through four tightly integrated platform engines:
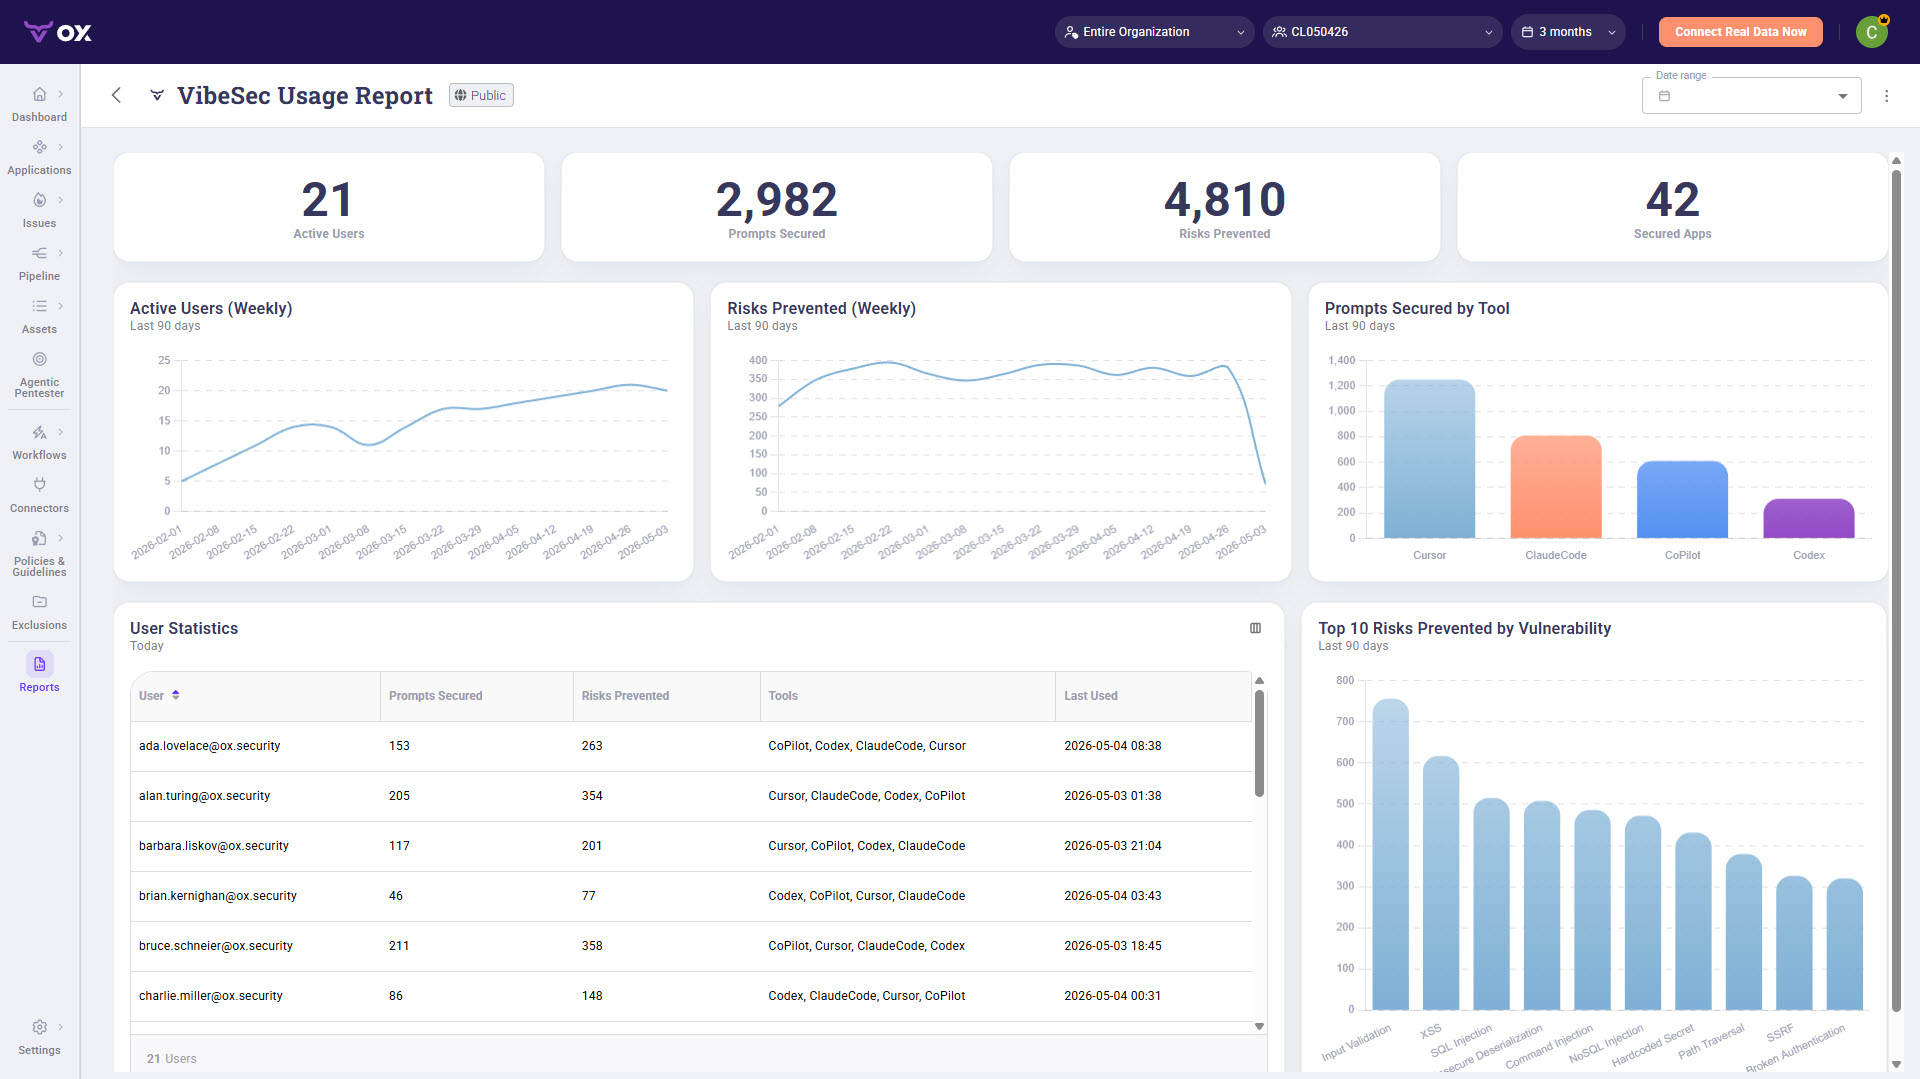
- Prompt-Level Prevention at Creation: Through OX VibeSec, the platform intercepts risks at the earliest possible moment: governing developer coding assistants, autonomous AI agents, skills, and Model Context Protocol (MCP) integrations before unvetted code or secret leaks ever enter the repository. OX customers using VibeSec saw a 70–90% reduction in newly introduced vulnerabilities (OX benchmark, 2026).
- Evidence-Based Exploitability: Using OX Code, the platform replaces theoretical severity scoring with deterministic reachability evidence, analyzing application call paths and execution topologies to discard non-reachable alert noise.
- Deterministic Code-to-Cloud Lineage: OX Cloud maps production misconfigurations and cloud runtime exposures directly back to their exact origin in source code, Infrastructure-as-Code templates, and pipeline definitions – ensuring remediations fix root causes rather than temporary symptoms.
- Autonomous Adversarial Validation: The OX Agentic Pentester simulates attack chains on demand against running pre-production environments, supplying developers with demonstrated proof of exploitability alongside verified fixes.
By consolidating prompt governance, code analysis, cloud enforcement, and autonomous validation into a single AINAPP, OX replaces point-tool sprawl and empowers security leaders to systematically drive Secure Velocity across the enterprise.
Driving Secure Velocity in the Post-CVE Era
The structural realities of modern software delivery have permanently reshaped application security. In an era dominated by AI-generated code, agentic workflows, complex build pipelines, and over-permissioned cloud resources, the risks that cause material incidents carry no CVE identifier to count. Consequently, evaluating a security program through gross finding volume or backlog burn-down rates no longer describes an organization’s true exposure.
Navigating this post-CVE landscape requires a shift in both metric and architecture:
- The Metric: Security leadership must adopt Secure Velocity, measuring the rate at which an organization delivers software that is safe at creation, uniting delivery speed and security control into a single operational standard.
- The Architecture: Moving Secure Velocity requires replacing point-tool sprawl and passive ASPM aggregation with a true AINAPP, a platform powered by a single risk model spanning code to cloud.
By focusing on prompt-level prevention, deterministic reachability evidence, and automated code-to-cloud lineage, security leaders transform their programs from reactive triage bottlenecks into active drivers of enterprise software delivery.
To see how a unified AINAPP eliminates alert noise and accelerates secure delivery, explore the OX Application Security Platform or book a demo with the OX Security team today.
FAQs
DORA measures deployment speed and operational stability. Secure Velocity builds on top of those baselines by incorporating pre-merge defect prevention, exploitable risk density, and flaw recurrence rates into a single engineering capability metric.
Legacy ASPM platforms sit downstream from creation and rely on ingesting metadata from third-party scanners. Without direct access to runtime execution paths and application call trees, they can only estimate theoretical risk rather than prove exploitability.
AI coding assistants introduce risks at machine speed, frequently generating hallucinated open-source packages, improper context assumptions, and unverified lifecycle hooks. These structural exposures often bypass traditional SAST checks because the syntax itself appears completely clean.
An AINAPP connects source repositories, build pipelines, non-human identities, and cloud runtime boundaries through a single, continuous graph. This allows security teams to trace runtime misconfigurations directly back to the exact developer commit, IaC template, or pipeline runner that created them.
ASPM remains useful for consolidating and deduplicating scanner output, and organizations running large point-tool estates will still see queue reduction from it. What it cannot do is prove exploitability or govern what happens before code is committed, so it is best scoped as a reporting layer rather than the control plane.
Prompt-to-cloud telemetry has to be instrumented first, because pre-merge prevention and exploitable defect density cannot be reported from post-commit scan data alone. Setting team targets ahead of that instrumentation produces numbers no one can trace back to an action.