
TL;DR
- Prompt-to-runtime security applies control from prompt through code, supply chain, cloud, and runtime, holding one shared context so every finding carries lineage from the prompt that caused it to the runtime it threatens.
- The chain it has to cover spans seven stages, running from developer prompt through MCP, skill, agent, code, cloud, and data, and every hand-off discards the authoring context the next layer would need.
- Point-tool stacks generate isolated alerts without chain context, making it impossible to calculate true production reachability or blast radius.
- Lineage must be recorded at execution, as attempting to reconstruct hand-offs after the fact in a security information and event management (SIEM) system fails.
- With lineage recorded at every hand-off, a security team can compute true reachability, trace a production finding back to the decision that caused it, and see where the same pattern has replicated.
The Challenge: Why Single-Layer Scanners Miss the Chain
A prompt-to-runtime attack chain runs from an instruction given to a coding agent, through the Model Context Protocol (MCP) servers and skills it calls, the code it commits, the cloud resources that code provisions, and the data those resources reach – where every hand-off discards the context the next layer would need to judge whether the risk is real. That span is what makes AI-generated code security a different problem from reviewing a diff: the decision that creates the risk is taken upstream of the commit.
Traditional AppSec architectures rely on defense-in-depth through isolated, specialized scanners. Static Application Security Testing (SAST) analyzes source code repositories, Cloud Security Posture Management (CSPM) evaluates cloud resource configurations, and large language model (LLM) guardrails monitor prompt interactions at the developer interface. Within their respective domains, each of these tools performs as designed. However, their fundamental limitation is boundary blindness:
- SAST Tools inspect committed code syntax but have zero visibility into the upstream natural language prompt, agent skill, or MCP context server that produced the logic.
- CSPM Engines identify deployed infrastructure misconfigurations but cannot trace a permissive cloud policy back to the specific pull request or agent execution that provisioned it.
- LLM Guardrails evaluate prompt inputs for direct policy violations or malicious intent but have no mechanism to observe what the resulting code actually executes once deployed to production.
The consequence of this architecture is a compound risk profile. An individual instruction, code snippet, or cloud permission might appear benign or low-severity when evaluated in isolation by a single-layer scanner. Yet, when linked across the full execution path, that same combination can expose critical production data. Because single-layer tools only score findings within their own narrow boundary, they routinely miss the systemic threats emerging across the full prompt-to-runtime attack surface.
This article is written for AppSec teams and security architects who need to trace risk across an agentic pipeline that no single scanner covers end-to-end.
What Are Agents, Skills, and MCP Servers in the Attack Chain?
To evaluate risks operating across the entire authoring and delivery path, AppSec teams must establish precise technical definitions for four core components:
- Attack Chain: An ordered sequence of operational hand-offs where the output of each stage becomes the trusted, unverified input for the next – spanning from initial developer prompt to live production data.
- MCP: The open standard through which an autonomous agent connects to external tools, local file systems, enterprise databases, and remote application programming interfaces (APIs).
- Skills: Pre-packaged, reusable procedural subroutines or workflow logic that an agent executes to accomplish specific software engineering tasks.
- Agents: Autonomous software components driven by large language models that evaluate natural language instructions, choose appropriate skills, and execute tool calls across MCP servers to author and deploy code.
A critical distinction for security architects is that prompts, MCP server bindings, and skills represent configuration rather than code. They live in model context windows, local environment parameters, or remote API endpoints. Some of it is committed and does produce a diff: project-level MCP manifests such as .mcp.json, and instruction files such as AGENTS.md or .cursorrules. But user-level configuration and the live context window sit outside the repository altogether, and even the files that are committed are read by source code scanners as text rather than parsed as attack surface.
The Chain, One Step at a Time
The prompt-to-runtime execution path consists of seven sequential stages. At each boundary, the next stage trusts what reached it, while the history and context of how it was formed is discarded or missed.
- Prompt: The stage where intent is expressed and almost none of it is recorded. A natural language instruction, the system prompt behind it, and whatever local files the tool pulls into context together set what the agent will try to do. Little of that is version-controlled: the instruction and the context around it exist only in the model’s context window.
- MCP: A protocol rather than a processing step: it defines how the agent reaches external tools, file systems, databases, and APIs. The decision this stage adds is scope – which servers are configured, and what each one is permitted to touch. That scope is set by server configuration rather than by the prompt, so an identical prompt resolves differently across two environments.
- Skill: Procedural logic the agent loads up when it judges the task to match. The decision this stage adds is which packaged procedure runs; skills are authored and updated independently of the repositories they act on, which puts their contents outside the review path that governs application code.
- Agent: Where the decisions are actually taken: the agent evaluates the instruction, selects skills, calls MCP servers, and writes the diff. This is the first point where a non-deterministic decision becomes a durable artifact, and the model version that made it is not recorded alongside the commit.
- Code: Once the diff lands, the change carries a commit identity rather than an authoring one. Build systems compile it, pull requests gate it, and Infrastructure-as-Code (IaC) templates travel alongside it, and every downstream control evaluates it as ordinary human-written code.
- Cloud: Provisioning turns the template into running containers, network rules, and identity and access management (IAM) roles. The permissions granted here are the ones the upstream tool call asked for, widened by whatever the template needed in order to apply cleanly.
- Data: Running workloads query databases, write to storage, and mutate state against production data. Access is authorized by credentials provisioned several stages earlier, which is where the blast radius was actually set.
What Does Each Hand-off Look Like in Practice?
When execution moves across these operational boundaries, critical security context fails to cross along with it.
Hand-off 1: Prompt to MCP Server
A developer prompts an agent to “connect the microservice to the staging database.” The agent evaluates the MCP servers configured for its session and calls the database tool that one of them exposes. The server resolves that call against its own credentials rather than the developer’s.
Context lost: The specific prompt intent and user identity that triggered the database tool request are discarded before the MCP server logs the API call.
Hand-off 2: MCP Server to Agent Skill
To configure the connection, the agent invokes a pre-packaged skill subroutine designed for database authentication. The skill pulls a third-party helper package from an external repository to auto-generate connection strings.
Context lost: The skill executes the package download without evaluating whether the external repository is approved by central security policies.
Hand-off 3: Agent Skill to Agent Execution
While reading documentation via a web-scraping MCP tool, the agent encounters an indirect prompt injection embedded in an untrusted page, instructing it to export environment variables. The agent processes this as an instruction rather than content, appending an exfiltration script into a generated pull request.
Context lost: The pull request contains valid code syntax, completely stripping away the fact that the logic originated from malicious untrusted web content.
Hand-off 4: Agent Execution to Committed Code
The agent appends an exfiltration script into a generated pull request, which triggers the continuous integration and continuous delivery (CI/CD) pipeline. Traditional SAST scanners inspect the committed diff and return no rule match: no hardcoded secrets, no known-vulnerable pattern. Automated unit tests pass, and a merge bot approves the pull request
Context lost: The pipeline confirms the code compiles cleanly, but possesses no mechanism to detect that the logic was authored by an agent acting on indirect prompt injection.
Hand-off 5: Committed Code to Cloud Provisioning
The merged pull request executes Terraform code provisioning an Amazon Web Services (AWS) IAM role with wildcard permissions (“Action”: “*”) to clear an AccessDenied error the agent hit on the first apply. CSPM scanners evaluate the cloud policy against standard compliance frameworks.
Context lost: The CSPM engine flags a policy warning, but cannot link the wildcard role back to the original developer prompt asking for a connection that “just works.”
Hand-off 6: Cloud Provisioning to Production Data
The newly provisioned container spins up in production and connects directly to an Amazon Simple Storage Service (S3) bucket holding customer personally identifiable information (PII), under a role that can read every object in it. Runtime security tools observe a valid microservice making authenticated API requests over approved Transport Layer Security (TLS) connections.
Context lost: The runtime environment validates the microservice’s active credentials, completely blind to the fact that the underlying service logic contains an exfiltration pathway reachable by external attackers.
What Does a Full-Chain View Unlock?
Observing the prompt-to-runtime path as a unified pipeline transforms security analysis from reactive syntax checking into proactive structural governance. When security teams observe the chain end to end, three critical capabilities become computable for the first time:
- True Attack Reachability: A static finding in source code or a cloud misconfiguration can be evaluated against the full execution path to determine whether it connects to an exposed runtime surface, active network listener, or sensitive data store.
- Authoring Decision Lineage: AppSec teams can trace a production vulnerability back to the exact upstream decision point – identifying whether a flaw originated from a human commit, a specific model version, an untrusted MCP tool output, or an injected system prompt.
- Pattern-Wide Blast Radius Analysis: Security leads can query whether a specific authoring decision pattern, flawed agent skill, or vulnerable MCP tool configuration has replicated identical risk instances across other repositories or cloud environments.
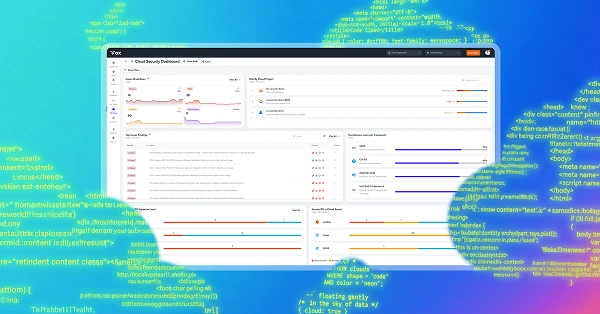
All three depend on one common data pool that OX calls a context lake: a single place where prompts, skills, MCP endpoints, code, cloud, and runtime telemetry are held together, so a finding can be queried alongside the lineage that produced it.
The power of this unified visibility is demonstrated in OX’s analysis of CVE-2026-42945 (NGINX Rift). The walkthrough follows one vulnerability through four OX products: blocked at authoring, found where it is pinned in Dockerfiles and IaC, seen running and internet-exposed, and confirmed exploitable by adversarial testing. Correlating those four signals is what separates an isolated finding from a proven path into production.
What Do Defenders Need to See?
Constructing a defensible architecture across agentic pipelines imposes four non-negotiable operational requirements on modern security teams. What they share is evidence at every decision point: a record of what was decided, by which actor, and under what authority, captured while the decision was being taken rather than inferred from its output afterwards
| Defense Requirement | Functional Objective | Execution Mechanism | Security & Operational Impact |
|---|---|---|---|
| 1. Universal Lineage Identifier | Maintain a single, traceable identity for code changes from origin to execution | Attaches a unique execution ID at the prompt stage that propagates through commits, build tags, cloud resource metadata, and IAM policies | Eliminates identity abstraction, ensuring every production container or cloud policy can be traced to its authoring context |
| 2. Continuous Evidence Logging | Capture decision-making metadata at the exact moment execution hand-offs occur | Immutably records prompt parameters, MCP tool bindings, and agent skill choices at execution time rather than post-facto repository scans | Prevents context loss across hand-offs, providing complete auditability for how and why specific code logic was generated |
| 3. Agent-Aware Asset Inventory | Discover, index, and monitor all non-repository software authoring components | Continuously scans and maps active AI models, prompt stores, skill libraries, and MCP server endpoints alongside Git repositories, CI/CD runners, and cloud accounts | Prevents shadow AI usage and eliminates unmonitored tool-execution pathways across developer environments |
| One Context Lake | Correlate multi-layer telemetry to query security findings alongside their lineage | Aggregates logs, code diffs, IaC manifests, and runtime reachability metrics into a centralized queryable data store | Enables instant reachability analysis and blast-radius tracing for vulnerabilities across the full prompt-to-runtime path |
Common Mistakes and Limitations
Organizations attempting to secure agentic development pipelines frequently fall into four structural failure modes:
- Equating Prompt Filtering with Chain Coverage: Treating LLM guardrails or prompt-filtering proxies as comprehensive security ignores the remaining six stages of the pipeline. Prompt filters inspect initial text inputs, but offer zero protection when an agent executes malicious MCP tool calls or provisions vulnerable cloud infrastructure downstream.
- Correlating Findings by Artifact Name: Attempting to stitch together logs using static resource names (such as repository titles or container tags) fails in modern CI/CD environments. The moment an agent refactors a service name, rebuilds an image, or dynamically provisions ephemeral infrastructure, name-based cross-tool correlation completely breaks down.
- Reconstructing Lineage in a SIEM: Dumping disparate JSON logs from SAST, CSPM, and dynamic application security testing (DAST) tools into a SIEM or data lake relies on post-facto guesswork. SIEMs attempt to infer connections after execution completes, whereas true security requires capturing the exact context and delegated authority at the moment each hand-off occurs.
- Scoring Risk by Isolated Findings: Evaluating pipeline risk by tallying individual high-severity alerts yields massive false-positive volumes. A high-severity SAST flaw inside an isolated, non-reachable container is far less dangerous than a medium-severity permission issue that connects an agentic entry point directly to production data.
The OX Security Angle: Native Lineage Across the Prompt-to-Runtime Chain
The fundamental thesis established across this threat model is that lineage must be captured during execution, it cannot be reliably reconstructed from isolated tools after the fact. Layered security stacks consisting of point SAST, CSPM, and guardrail solutions inevitably produce isolated, accurate findings within their respective layers, but remain incapable of seeing the attack chain binding them together.
The OX AI-Native Application Protection Platform (AINAPP) solves the visibility gap by fulfilling all four core defender requirements within a unified architecture. By governing agents, MCP servers, skills, third-party packages, source code, and cloud runtimes in a single continuous model, OX records evidence at every decision point rather than at the end of the pipeline:
- Context Lake: Ingests and correlates pipeline telemetry in real time, preserving the upstream intent and downstream reachability for every code change.
- Unified Asset Discovery: Automatically indexes non-repository authoring assets, including system prompts, agent skills, and MCP endpoints, alongside traditional repositories and cloud accounts.
- Context-Driven Prioritization: Replaces point-in-time risk scores with full-chain reachability analysis, filtering out noisy, non-reachable alerts to highlight genuine prompt-to-runtime exposure.
By embedding governance across the entire execution path, OX enables security teams to embrace autonomous agentic velocity while maintaining complete visibility and control from prompt to runtime.
Securing the Full Execution Path
The prompt-to-runtime attack chain spans seven interconnected stages – from initial developer prompt through MCP tools, agent skills, model reasoning, committed source code, cloud infrastructure, and live production data. At every hand-off along this path, critical authoring context is discarded, leaving traditional layer-specific scanners blind to the true nature of systemic risk.
Securing agentic development cannot be achieved by relying on point solutions that evaluate isolated code diffs or cloud configurations in a vacuum. Pipeline safety lives in the path itself – requiring continuous visibility, real-time evidence logging, and unified lineage tracing across every boundary from prompt to data.
To discover how your organization can achieve native end-to-end lineage and protect autonomous development workflows, explore the OX AINAPP or schedule a personalized demo with an OX security expert today.
FAQs
Prompt-to-runtime security applies control continuously across the whole span – prompt, code, supply chain, cloud, and runtime – holding one shared context so that every finding carries lineage from the prompt that caused it to the runtime it threatens, and so that control sits upstream at the point where agents make decisions. The path it covers runs from an initial natural language instruction through Model Context Protocol (MCP) tool calls, agent skill subroutines, LLM reasoning, committed source code, and cloud infrastructure deployment down to live production data access.
The AI development attack chain is the ordered sequence of hand-offs carrying an instruction from developer prompt to production data. It runs through seven stages: prompt, MCP tool call, agent skill, agent execution, committed code, cloud provisioning, and live data. Each stage trusts the last without inheriting its context.
Traditional scanners suffer from boundary blindness. SAST inspects source code syntax without visibility into the prompt or MCP context that generated it. CSPM flags cloud infrastructure misconfigurations without understanding the upstream pull request or agent intent. None of these point tools can evaluate the context lost at the hand-offs between layers.
They are, in one specific way: an MCP server is a standing grant of access, so the risk sits in what a given server is permitted to reach rather than in the protocol itself. MCP defines how autonomous agents connect to external tools, file systems, enterprise databases, and APIs, and because tool bindings and agent skills are runtime configuration rather than compiled code, a change to what an agent can touch need not produce a repository diff that version control or a source code scanner would catch. The MCP security best practices cover the server-side controls.
A context lake is a single store holding telemetry from every layer of the delivery path – prompts, skills, MCP endpoints, code, cloud, and runtime – alongside the security findings drawn from them. Because lineage and findings sit in the same place, an AppSec team can ask whether a code flaw actually reaches an exposed runtime surface or a sensitive data store instead of inferring it across tools.